How Does AI Actually Learn?
While AI tools like chatbots and spam filters often feel magical, computers don't learn through human consciousness or personal experience. Instead, they rely on machine learning algorithms that analyze data to identify patterns, adjust mathematical parameters, and generate useful predictions.
Deepak Singhal
Introduction
Artificial intelligence can seem almost magical.
You type a question into an AI chatbot and receive an answer. You upload a photograph and an AI system can identify objects. Streaming platforms recommend movies, email services detect spam, and voice assistants can understand spoken commands.
But an obvious question sits behind all of this:
How does a computer actually learn?
The word learn can be misleading.
AI doesn't learn in exactly the same way a person learns at school. It doesn't have human experiences, emotions or consciousness. Instead, many modern AI systems use machine learning, a branch of artificial intelligence in which algorithms process data and adjust mathematical parameters to recognize patterns and produce useful predictions or outputs.
Understanding this process doesn't require advanced mathematics.
Let's break it down.
First, What Does “Learning” Mean for AI?
Imagine you want a computer to identify whether an email is spam.
One approach would be to write thousands of rules:
- If an email contains certain words, mark it as spam.
- If it comes from a suspicious address, mark it as spam.
- If it contains too many links, mark it as spam.
This can work, but manually creating rules for every possible situation becomes difficult.
Machine learning takes a different approach.
Instead of explicitly programming every rule, developers provide the system with examples and an algorithm that can learn patterns from those examples.
The model makes predictions, its performance is measured, and its internal parameters are adjusted to reduce errors.
Over many iterations, the model can become better at the task.
That's the basic idea behind machine learning.
1. Everything Starts With Data
Data is one of the most important ingredients in machine learning.
Depending on what an AI system is designed to do, its training data might include:
- Text
- Images
- Audio
- Video
- Numbers
- Sensor information
- User interactions
- Other structured or unstructured information
For example, an AI system designed to recognize cats in photographs could be trained using a large collection of images containing cats and other objects.
An AI system designed for language tasks might process large collections of text.
The important point is that the data provides examples from which the model can identify patterns.
IBM describes training data as information used to teach machine-learning models to recognize patterns, make predictions or generate content.
2. More Data Doesn't Automatically Mean Better AI
It might sound logical that feeding an AI model more data will always make it better.
But that's not necessarily true.
Data quality matters.
Imagine training a system to recognize different types of fruit using thousands of poorly labelled photographs.
If many apples are labelled as oranges, the model may learn incorrect relationships.
Similarly, incomplete, noisy or unrepresentative data can affect the quality of a model's results.
This is why AI development involves activities such as:
- Collecting data
- Cleaning data
- Preparing data
- Labelling data when necessary
- Checking data quality
- Evaluating whether the data represents the intended task
IBM notes that poor-quality data can introduce noise and bias, while high-quality data can help models produce more reliable results.
So a useful principle is:
AI learning depends not only on how much data is available, but also on what that data contains.
3. The Model Makes a Prediction
Once training begins, the AI model processes examples.
At the beginning, its internal parameters may not be well adjusted for the task.
So its predictions can be poor.
Imagine showing a model an image of a dog and asking:
“What is this?”
The model might initially produce the wrong answer.
The important part is what happens next.
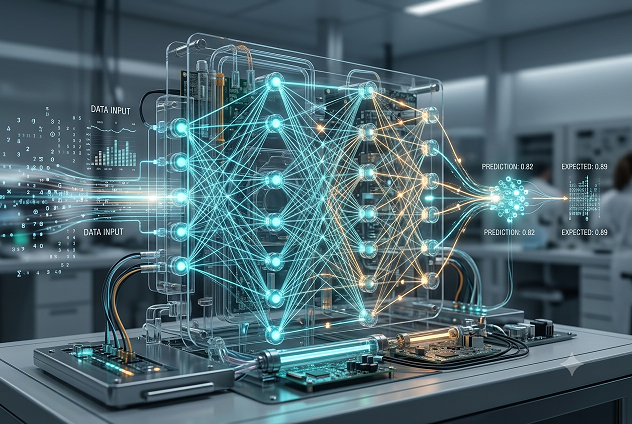
The system compares its prediction with the expected result and calculates how far it was from the desired output.
That difference is commonly represented using a loss function.
The training process then uses this information to adjust the model's parameters.
4. The Model Adjusts Its Parameters
This is one of the most important parts of AI learning.
Modern machine-learning models can contain many adjustable parameters.
In neural networks, these include weights and biases.
A simplified way to think about them is as numerical settings that influence how strongly different pieces of information affect the model's output.
During training, algorithms adjust these parameters so that the model's predictions become more useful.
The process can happen repeatedly:
Input → Prediction → Measure Error → Adjust Parameters → Try Again
Then the cycle repeats.
IBM describes model training as the process of adjusting model parameters to improve performance on training data.
5. Repetition Is a Major Part of Learning
AI models usually don't become useful after seeing one example.
They process many examples through repeated training steps.
A complete pass through a training dataset is commonly referred to as an epoch.
Depending on the model and training setup, the system may go through many epochs.
Think of learning to recognize handwriting.
Seeing one handwritten letter probably isn't enough.
But seeing thousands or millions of examples can allow a model to identify recurring characteristics such as shapes, curves and relationships between pixels.
The model isn't memorizing a simple list of answers.
It is attempting to adjust its mathematical parameters so that it can identify patterns across examples.
6. Neural Networks Help AI Learn Complex Patterns
Many modern AI systems use artificial neural networks.
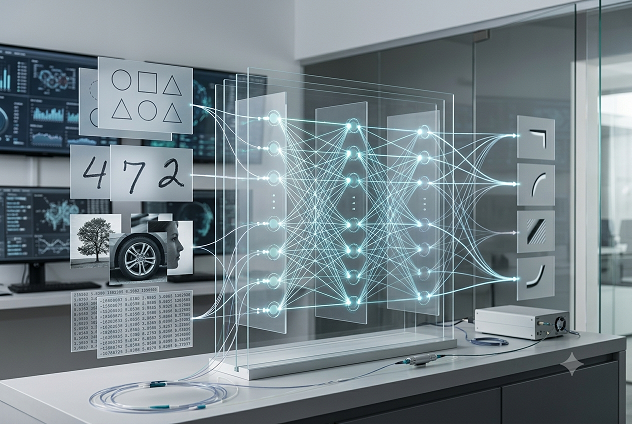
A neural network contains interconnected layers of computational nodes.
A simplified network can be thought of as having:
Input layer → Hidden layers → Output layer
Information passes through these layers while mathematical operations transform it.
Each connection has associated weights, and these weights are adjusted during training.
Deep learning uses neural networks with many layers, allowing models to represent complex patterns in large datasets.
For example, in image recognition, earlier layers may respond to relatively simple visual patterns, while deeper layers can combine information into more complex representations.
This layered processing is one reason deep-learning systems can handle difficult tasks involving images, language, audio and other forms of data.
7. Different Types of AI Learning Exist
Not every AI model learns in exactly the same way.
Three commonly discussed machine-learning approaches are supervised learning, unsupervised learning and reinforcement learning.
Supervised Learning
The model learns from examples where the desired output is known.
For example:
Image → “Cat”
Image → “Dog”
The model learns relationships between inputs and labelled outputs.
This approach is commonly used for classification and prediction tasks.
Unsupervised Learning
The model works with data without predefined labels and attempts to identify patterns, groups or relationships within it.
For example, an algorithm might identify groups of customers with similar behaviors.
Reinforcement Learning
The system learns by interacting with an environment and receiving rewards or penalties associated with actions.
The goal is to learn a strategy that produces better outcomes over time.
These approaches can also be combined in complex AI systems.
8. What About ChatGPT and Other AI Chatbots?
Generative AI adds another interesting layer to this discussion.
Large language models are trained on very large collections of text and learn statistical patterns in language.
During training, a language model learns to predict tokens—the units into which text is divided—based on surrounding context.
For a simplified example, imagine:
“The sun rises in the ___.”
A language model learns that words such as “east” are strongly associated with that context.
But modern language models learn vastly more complicated patterns across enormous amounts of text.
After initial training, models can also undergo additional stages such as fine-tuning and post-training to improve their usefulness for particular tasks and interactions.
9. AI Doesn't Necessarily “Understand” Like Humans
This is an important distinction.
When we say that an AI model “understands” something, the word is often being used informally.
A model can identify patterns and produce remarkably sophisticated outputs without having human-like consciousness or personal experiences.
For example, a language model can generate an explanation about happiness without actually experiencing happiness.
It can describe a rainy day without having stood outside in the rain.
This distinction matters because impressive output doesn't automatically mean the system thinks or understands in exactly the same way a human does.
10. How Does AI Know If It Is Getting Better?
Training isn't simply about repeatedly processing data.
Developers also need to evaluate the model.
A common approach is to divide available data into different portions, such as:
- Training data
- Validation data
- Test data
The training data helps adjust the model.
Validation data can help with tuning decisions during development.
A separate test set can then provide an indication of how the model performs on data it wasn't trained directly on.
This is important because a model can perform extremely well on examples it has already seen but perform poorly on new examples.
That problem is known as overfitting.
The broader goal of machine learning is not simply to perform well on training examples.
It is to generalize—to apply useful patterns to new data.
11. Why AI Can Still Make Mistakes
If AI learns from data, shouldn't it eventually become perfect?
Not necessarily.
AI models can make mistakes for many reasons.
The training data may contain:
- Errors
- Missing information
- Bias
- Ambiguous examples
- Limited representation of certain situations
The model itself may also have limitations.
And real-world situations can be different from the data used during training.
This is why AI outputs should not automatically be treated as facts.
For important decisions—particularly in areas such as healthcare, finance, law or safety—appropriate human expertise and verification remain important.
A Simple Example of AI Learning
Let's imagine we want an AI model to recognize whether a photograph contains a bicycle.
Step 1: Collect examples
Thousands of images are gathered.
Step 2: Prepare the data
The images are processed and, where required, labelled.
Step 3: Train the model
The model examines examples and produces predictions.
Step 4: Measure errors
Incorrect predictions contribute to a loss measure.
Step 5: Adjust parameters
The training algorithm changes model parameters to improve future predictions.
Step 6: Repeat
The process happens across many training examples and iterations.
Step 7: Test
The model is evaluated using data it wasn't directly trained on.
Step 8: Deploy
If the results are suitable for the intended use, the model can be incorporated into an application.
That's a simplified picture of machine learning, but it captures the central idea.
So, Does AI Really Learn?
Yes—but the word “learn” needs context.
Machine-learning systems learn statistical patterns from data by adjusting mathematical parameters during training.
They don't learn exactly as humans do.
They don't automatically possess human judgment, life experience or common sense simply because they have processed enormous amounts of information.
The strength of modern AI comes from combining:
Data + Algorithms + Computing Power + Training + Evaluation
When these pieces work well together, AI models can perform remarkably complex tasks.
Inkauras Insight
AI doesn't learn by simply “reading information.” It learns through a mathematical training process in which patterns in data influence adjustable model parameters.
The basic cycle is surprisingly simple:
Data → Prediction → Error → Adjustment → Repetition → Evaluation
What makes modern AI impressive is the scale and complexity at which this process can happen.
Large datasets, powerful computing systems and sophisticated algorithms allow modern models to learn patterns that would be extremely difficult to program manually.
Final Thought
AI can sometimes look like a mysterious black box.
But at its foundation, much of modern machine learning follows a relatively understandable idea:
Give the model data, let it make predictions, measure how well it performs, adjust its parameters and repeat the process.
Of course, the real systems are far more complicated than this simplified explanation.
But understanding the basic learning cycle gives us a better way to think about AI—and also helps us understand why data quality, evaluation and human oversight remain so important.
The next time an AI system gives you an impressive answer, remember:
Behind the conversation is a very large mathematical system that learned patterns from data.
Important Note
This article is intended for general educational and informational purposes only. It provides a simplified explanation of machine learning and AI and does not describe the architecture or training process of every AI system.
AI technologies differ significantly in their training methods, data, architectures, objectives and evaluation processes. Readers should consult technical documentation or qualified professionals when detailed information is required for a specific AI system or application.
Share your views in the comment section.
Rate this article
Sign in to rate this article.